Trending
CoreWeave leasing 22.5MW from atNorth data center in Denmark CTIA, Big 3 US carriers warn that support for D2D in 5G bands could hurt network performance First building at Project Jupiter data center campus in New Mexico topped out La Caisse snaps up 49.9% stake in Bell Canada’s tower unit AI and the Physician Shortage: The Strong Case for Urgent, Careful Progress Sponsored: The extinction of data breaches: Degauss, destroy, recycle 520MW data center planned in Eatonton, Georgia DCD Studio: Who decides the future of AI compute? with Piotr Tomasik, TensorWave Zocdoc Acquires Sohar Health | Diverge Health Merges with Medical Home Network Rethinking the Blind-Mate Connection Oracle will offer Google’s TPU AI chip via OCI An education on transfer switch neutral options easyJet to offer Starlink in-flight WiFi from next year STTGDC secures $590m green loan for Tokyo data centers Crypto exchange Binance to close Bitcoin mining pool next month

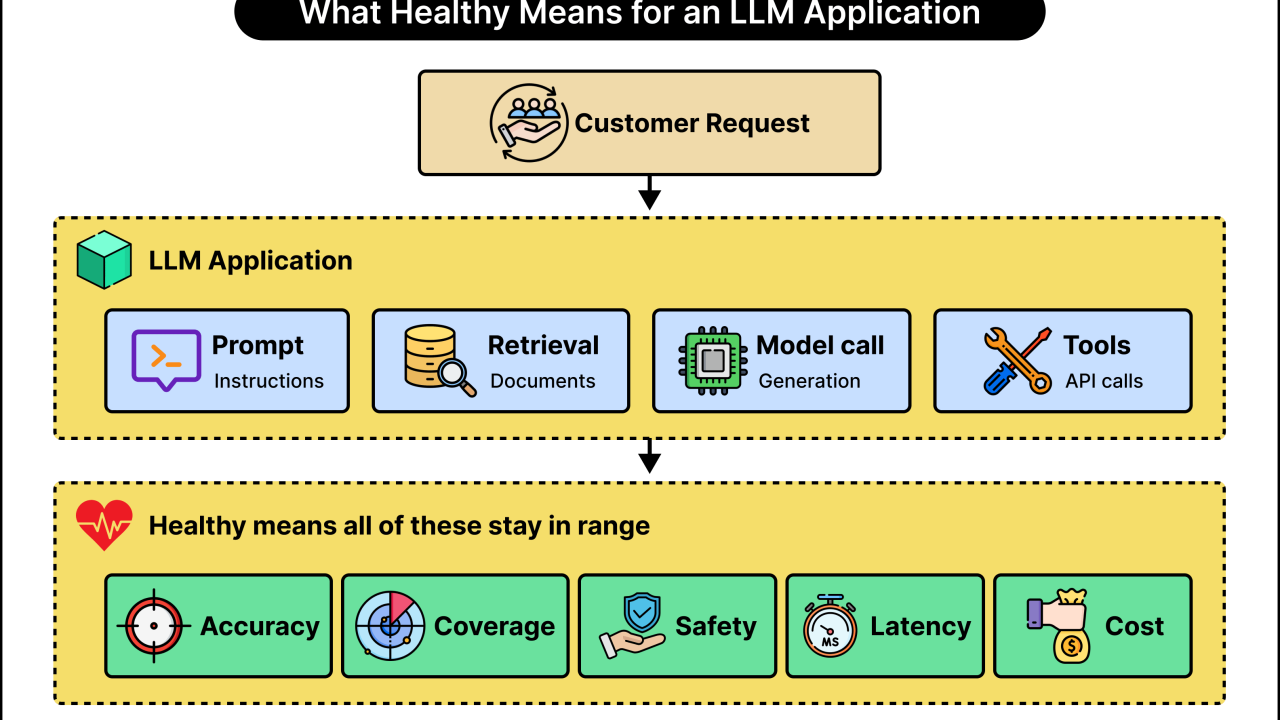
LLMs as a Judge: How to Know if Your LLM is Healthy

In the instance that you distribute AI agents without conducting offline verification, the responsibility of testing falls upon your users. Acquire the functional framework for assessing production-ready AI agents prior to deployment. Obtain the manual to understand how to:.

Construct test datasets with annotations encompassing primary usage scenarios, rare instances, and contrary inputs. Create evaluators that reflect actual business impact, including deterministic and LLM-as-a-judge components. Monitor the entire process of multi-agent workflows throughout experimentation in order to identify and rectify failures before they affect users.

Maintain model stability by ensuring your offline testing environment remains consistent with the production setting. Retrieve the tutorial. Like other software systems we’ve come across, Large Language Models (LLMs) are also programs.
 

Join the conversation

Your email address will not be published. Required fields are marked *