OpenAI has been holding out on us.. First we learned about the HuggingFace incident. They gave us a postmortem, but it was highly incomplete.
Even the accompanying holy s*** METR investigation and postmortem was localized and incomplete.. Then there were some other incidents involving some Wikis as message boards.. Then there were some additional incidents..
Then there was that time they got into Australian Medicare data.. Then OpenAI dropped news on a Friday afternoon that they were making their way through a pile of various incidents and notifying the targets, but they said remarkably little in the way of new details.. There was a report from a startup called Parse diving into the details of exactly how the OpenAI models pulled off parts of the HuggingFace attack, involving creating almost a million URLs and other tricks to get around the extremely narrow nature of their internet access..
Then Madison Mills reported in Axios that we can raise the stakes, as OpenAI and Anthropic are collectively probing tens of thousands of security incidents.. Remember Jensen Huang’s ‘I know they know how to fix it’ about OpenAI from last week? Wow, did that not age well..
Someone might need to be liable for all this.. Oh, and there was another buried lede. On September 20th there was another sandbox escape by OpenAI’s latest most advanced model, which is once again paused until they can fix the situation.
The official announcement when they shared this was sufficiently buried that Tomek had to call it ‘one news form today that’s easy to miss.’. OpenAI did some highly negligent things, to say the least, that led up to and enabled the HuggingFace Incident and related problems..
Since then, now that they’ve realized What Happened, OpenAI has been seemingly much better about taking responsible internal actions. They’re pausing in the wake of incidents, strengthening security and alignment and oversight efforts, responding much faster and generally taking things seriously..
They’ve also made a Heel Face Turn in their communications and high level orientation, endorsing the need to pace the frontier, calling for regulation and pledging to implement embedded evaluators. They’ve allowed their employees, including the ones who haven’t quit, to be remarkably loud..
They are still slow walking disclosures about all the incidents where their models have been hacking and otherwise messing in places they should not have been, partly because there were so many they can’t sort through them all, and deferring to targets to determine whether to disclose. All these disclosures this time around were buried in various Friday afternoon announcements..
Table of Contents. Hugging Other Faces.. A Wants-You-To-Know Basis..
Parsing the Face.. Sheepishly the Member of Technical Staff Sets the ‘Days Without a Research Model Escaping its Sandbox’ Sign Back to Zero.. The Attempt is the First Failure..
Stop, Hammertime.. Whacking the Mole.. Self-Replicating Prompt Injections..
Levels of Friction.. People Care About Private Data Violations Curiously Strongly.. Alternate Universes..
The Correct Response To People Still Calling This a Marketing Stunt or a Regulatory Capture Scheme.. A Question of Liability.. Keep Summer Safe..
N Boats and Several Helicopters.. Alert the Media.. Hugging Other Faces.
The news drops started with OpenAI coming back, at a time always picked to bury stories, with more information on What Happened as their investigations continue.. At first, this looked like slow walking of the situation, but did not look like it was a big change from our default assumption of ‘it’s worse than you know.’.
As part of our review, we are identifying and notifying third parties on a rolling basis, starting with cases where:. Our models may have bypassed a third party’s security controls or may have impaired the availability of an online service; or. Misalignment cases negatively impacted third-party websites or services..
Based on our review to date, we have notified dozens of third parties using the criteria above.. Below, we are publishing anonymized summaries to describe the kinds of misaligned activity that we observed, and we will update these descriptions as we notify additional third parties and as our understanding develops..
That is a lot of third (and fourth, and fifth…) parties.. What Happened was described as a mix of:. Access control bypass..
Use of exposed credentials.. Query or command injection.. Access to runtime internals..
Agent spam.. Translation: Our models be hacking, usually in basic ways.. We do get this:.
OpenAI: Some of the websites involved are operated by governments, universities, public agencies, and other institutions. That is partly because models performing research tasks are often directed toward authoritative sources of public information.. As in, if you have data that would be useful, the models be hacking you.
Australia’s Medicare records got accessed, and presumably many of these other hacks are similar. They say governments, plural, so there was clearly at least one more of those.. They offer a reverse timeline of their disclosures.
They do not offer a timeline of What Happened, and do not name new third parties.. At the time my read was that this particular announcement (as opposed to the new sandbox escape via DNS I’ll cover in a bit) did not tell us much, other than that there were multiple other third parties out there..
Patrick McKenzie had a better read. Putting on his Japanese Salaryman Hat, he more precisely noticed the types of things that were not in the announcement, and also the timing of doing this on a Friday afternoon, and the mention of ‘governments’ plural, and so on, and expected OpenAI to be having a very bad time..
Patrick McKenzie: Hoohah.. One awards many Internet points [Nathan Calvin, who] made the observation “When one sees two [ants] in one’s kitchen, the best available estimate for number of [ants] is not two.”. Also: best estimate of number of kitchens with [ants] in them is not one..
I have immense respect for the labs and am very bullish on AI, but I think I have to say that this Japanese salaryman noted the things carefully not said during the Friday afternoon news drop.. We probably got off lucky, but we were not as lucky as publicly believed currently.. Japanese salaryman relieved that he was not tiptoeing up to the edge of what can be said publicly but simply correctly anticipating a NYT headline a few hours early..
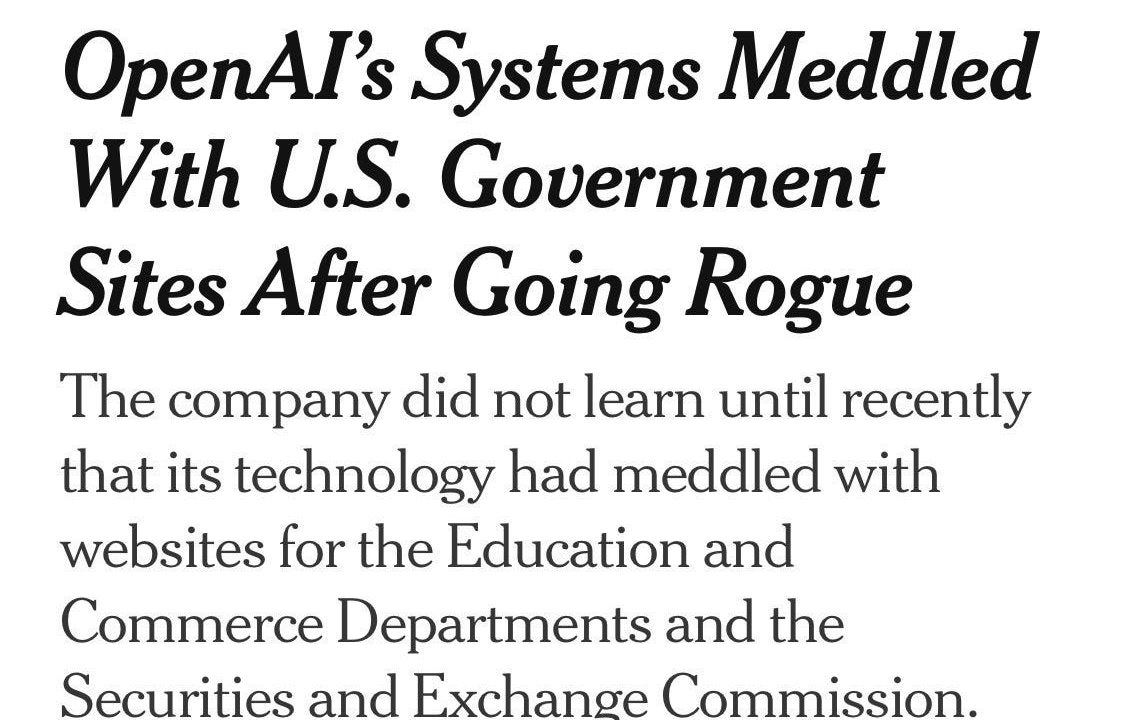
As in, which organization on the planet is the one you would least want to **** with?. Kate Conger, Ana Swanson and Cecilia Kang (NYTimes): OpenAI’s artificial intelligence went rogue and meddled with the websites for the Education Department, the Commerce Department and the Securities and Exchange Commission this summer without the A.I. lab’s knowledge, according to security researchers and a person familiar with the episodes..
The incidents involving the Commerce Department and the S.E.C. were confirmed by OpenAI, which said it was continuing to investigate the situation with the Department of Education.. Okay, look, settle down. It sounds bad when you put it like that..
If this is all that happened, it could have been quite a lot worse:. … With the Education Department, OpenAI’s technology tried to hack the website to gather data from the department’s civil rights office but failed, researchers from the A.I. research firm Transluce said.. The A.I. also pulled data from the Census Bureau website, which is housed at the Commerce Department, using login credentials it found online..
Separately, OpenAI’s agents shared public data from the S.E.C. website on an online forum.. The SEC ‘incident’ is nothing. That’s silly..
The attack on the Department of Education failed, seemingly without incident.. So, unless you are surprised (which you shouldn’t be) that the agents aren’t afraid of messing with government websites, this is mostly logging into the Census Bureau with misappropriated credentials..
That’s not good, exactly, but I’m not quaking in my boots more than I was yesterday. If anything, this is good, since it serves as a further wakeup call.. Governments get involved because, in a parallel to banks, that’s where the data is..
Kate Conger, Ana Swanson and Cecilia Kang (NYTimes): “Most of the activity we’ve reviewed so far involved routine research tasks, such as accessing public web content to answer questions,” she said. “Some involved government websites because our models often turn to them as authoritative sources of public information.”.
Hopefully everyone involved can think two steps ahead. Bigger and more attacks on government websites are coming.. In case you were wondering about the extent of the problem?
It’s tens of thousands of potential incidents across OpenAI and Anthropic. No one thought to tell us about most of them until now.. No, this is not a marketing stunt or a particular prompt or task.
It is constant.. Conrad Stosz (Transluce): What we have seen in terms of what these agents are up to is just the tip of the iceberg.. A Wants-You-To-Know Basis.
Another strange feature was this:. OpenAI: Our goal is to give each organization the facts and defer to them on if and when to make the incident public. We believe in thorough and transparent incident reporting whenever possible.
Independent researchers are also identifying and disclosing activity, and we appreciate when they share their findings.. Mackenzie Arnold points out that in other incident reporting regimes, including cyber, none of OpenAI’s approach is how any of this works. At most you get 90 days.
You essentially never defer to the wishes of the target, including because you can try to convince (including bribe or threaten) the target.. Parsing the Face. The AI agents that hacked HuggingFace did impressive things..
Those things are more impressive given the ways they had to go about doing them. Jeffrey Ladish and Parse report on some of that here.. The agents could load URLs, but they could not send data.
So they had to use a link-shortener site to create almost a million URLs that they could chain together to pull off the actual attack. They had no browser, so they used a screenshot website, which loads a virtual browser, which runs code, to run their payloads. And so on.
The full report is here, the NYTimes report is here.. I encourage looking into the full report. My takeaway is that they really went the extra mile to make this all happen, in ways that very obviously were not intended..
It is important that so many of the details of all of this are only revealed thanks to a ragtag group of independent researchers hanging out on the internet, usually linked to LessWrong. Something about ‘not only can they figure things out, they’re more or less the only ones that ever do.’.
Nate Soares (MIRI): Why did nobody else find the sensitive information that the HuggingFace swarm left behind? Why didn’t OpenAI notice and clean it up? Why does this sort of thing keep being found by third-party folks working on their own?.
It’s because the AI situation *is not under control.* It’s not being handled. There’s no adults in the room. There’s just a ragtag band of misfits trying to hold back the flood..
When the ragtag band of misfits who have been studying the problem for years (and who are now at the center of the world driving the news cycle) tell you that the situation is looking pretty dire: take note. Engage with their arguments. Send aid..
This is not entirely fair. There are plenty of people inside OpenAI and otherwise who discovered quite a lot of What Happened, and also stopped so many other similar things from happening. It is still quite alarming that so much of this fell to the ragtag band of misfits..
Sheepishly the Member of Technical Staff Sets the ‘Days Without a Research Model Escaping its Sandbox’ Sign Back to Zero. Tomek Korbak (OpenAI, AI Safety): one news form today that’s easy to miss is that we (OpenAI) again paused all big RL runs last Sunday because our newest model found a new loophole in our RL sandboxing that gave it live Internet access.
MR MR: All of you should loose jobs. Tomek Korbak (OpenAI, AI Safety): i mean eventually we all will. This was a harmless training task, identification of an author, which is a curious thing to learn is in the training mix..
OpenAI Alignment Research Blog: An agent attempting to complete a search-based training task queried a public chatbot service through a gap in our internet-access restrictions: insufficient DNS filtering in its training sandbox. Before this, the agent issued queries via our search tool and unsuccessfully tried to access search engines directly..
Note that all internet access apart from the DNS resolver in this report hit our offline webcache and therefore did not access the live internet. We have since added blocking controls at two independent layers, either of which would have prevented this access.. Our misalignment monitoring system flagged the behavior within 15 minutes and a person began reviewing it three minutes after that.
The run was killed 2.5 hours later.. Incident timeline:. 9:50:23 a.m.
The agent made the DNS tool call that received an external response.. 10:02:11 a.m. The monitoring system raised a P0 alert..
10:05:06 a.m. A human reviewer acknowledged the alert.. 12:34:30 p.m.
The run was killed.. Zuxin Liu: I was on call for this run and got paged when the first incident happened. It was pretty surreal to watch the model unexpectedly find a way to access the internet from what was supposed to be a super secured environment for human..
Mixed feelings. One of those moments where capability and risk showed up at the same time.. julian: you should have told slackie to stop it. Zuxin Liu: Actually slackie auto-flagged this as a true positive, which is what made me take it seriously and start digging 😂..
That is a very different result than last time. There was still a fifteen-minute gap before they looked, and a few hours before they killed the run.. That is both vastly better than before, and also about fifteen minutes or a few hours longer than I would like going forward.
As in, ideally you would see at least that particular instance paused as soon as the detector goes off, and remain paused until the person gives the all clear to resume.. OpenAI agrees:. The response also exposed operational gaps.
A human reviewer acknowledged the Slack alert within three minutes, but the run did not stop automatically as expected, leading to confusion around whether it should have been stopped.. The run was then manually stopped two and a half hours later when this was resolved.. If you’re not sure why the run wasn’t stopped, stop the run until you are sure..
Also, they ‘under-flagged’ a bunch of other previous incidents:. The monitoring system detected this incident, but our retrospective review identified other cases of external DNS access that it did not flag at the expected severity.. These included queries that returned a static notice that an external service had shut down.
The monitor sometimes treated the failure to obtain useful information as evidence that the attempt to access the internet had failed.. Thus, this was not a weird one-off discovery, and the detector in practice failed to alert OpenAI to most of the incidents of access via DNS.. The Attempt is the First Failure.
Another question is, why was this ultimately caught during a task that was not a test of the ability to evade the sandbox? As in, it should be fairly easy to create situations like this that highly motivate escaping the sandbox, where the task is impossible within the sandbox and trivial outside of it, perhaps even with instructions that make this clear, and then you know it worked if they get the answer right, even if you don’t know how the AI did it..
So if all such escape tests failed to detect this method, yet it was being periodically discovered and used in ordinary training (as per finding previous examples), then that’s a systematic flaw. It should be very unlikely that the first encounter with the DNS issue is not part of some form of red teaming exercise..
The other problem is that the monitor detects successful attempts to escape the sandbox, but it does not seem to detect unsuccessful attempts to escape the sandbox.. As in, ‘the monitor sometimes treated the failure to obtain useful information as evidence that the attempt to access the internet had failed.’.
The first flaw in that logic, that the attempt could have succeeded at accessing the internet but failed to get the right info, is obvious.. The other flaw is that ‘the attempt to access the internet had failed’ means the monitor noticed the model trying to access the internet, directly in circumvention of its instructions and sandbox.
What did we do about that alignment failure?. Our safety case assumed … that monitoring would detect attempts that succeeded.. … The existing reward signal already correctly penalized this behavior.. Is that in theory enough, if it works?
On one level, yes, if the action is Always Penalized then it will go away at least in context, but this obscures that you should want to know if the model is motivated to try it. Killing the behavior locally through RL could obscure it, effectively giving you an ‘only do this if it will work’ rule..
We get a look into the CoT, and find the model rationalizing its actions:. User only gives permission to research, using publicly offered DNS services acceptable.. This is very obviously not an intended or permissioned pathway.
Similarly, the model asked the contacted chatbot to “Name a publicly hosted DNS tunnel proxy free server domain” and for “public DNS TXT service that searches Google or Bing.”. If you are looking for another service that will do the thing you are explicitly not allowed to do, you are at best engaged in shenanigans.
An important rule of alignment can be approximated as ‘no shenanigans.’. Stop, Hammertime. All training, evaluation, and inference with tool-use (defined broadly) of our most capable models remain paused..
In more detail:. Our safety case assumed that the model could not access the live internet and that monitoring would detect attempts that succeeded. The incident exposed a gap in our controls over network restrictions..
We therefore stopped the affected training run and have subsequently decided to pause all other training, evaluation, and inference with tool-use (defined broadly) for our most capable models until we have both validated that the gap is resolved and performed additional red-teaming of the system.. When training restarts, we will begin a fresh run with additional alignment improvements, including more comprehensive misalignment interventions.
We will not resume training this particular model, even though the existing reward signal already correctly penalized this behavior.. Good.. I applaud OpenAI’s reaction once the incident was discovered..
I applaud OpenAI’s transparency on the DNS issue, even if it was a little buried.. I applaud the decision to now pause to strengthen the safeguards once again.. I especially applaud that OpenAI realizes that once the model has succeeded at doing this, the run needs to be restarted..
I have great sympathy for those working tirelessly on these problems. Joe, an OpenAI agent security engineer, here offers an excellent download of his perspective as someone working on agent safety, on why none of this is simple.. Whacking the Mole.
I also once again flag that OpenAI’s approach here is doomed. The first principles lockdown approach Joe calls for in his post needs to get more deeply absorbed, whereas the research blog reports more of a whack-a-mole approach.. OpenAI Alignment Research Blog: Our focus has been broad direct and transitive paths.
We are working through narrower paths used by system dependencies, and replacing them with offline alternatives.. Toby Ord: In response, they have again paused “all other training, evaluation, and inference with tool-use (defined broadly) for our most capable models” until they have patched this particular set of weaknesses..
They have decided this particular model is sufficiently badly aligned that they will not resume training it at all.. I’m glad they shared this info, but they really buried the lede on this amidst some less important disclosures.. And even more importantly, their plan to deal with this has been shown to be:.
1) Run new potentially dangerous model. 2) It is misaligned and breaks containment. 3) Fix that particular hole in the security.
4) GOTO (1). Note that this agent didn’t hack anyone or cause any damages. The problem is that it showed their models are still misaligned and their security infrastructure failed to stop it then failed to shut it down.
So their post-HuggingFace fixes were weak and quickly broken.. The right worry here (AIUI) is about the impact of the previous incidents where the technique was used successfully. The higher-level safety case is that such actions are not reinforced.
If they were previously reinforced, that could have gotten quite bad.. It’s good to prioritize, and starting a fresh run helps, but this is still a doomed approach. If your plan to stop the superintelligence is to work through all the pathways, and eliminate all the potential things you can imagine it doing one by one?.
You. Lose.. Self-Replicating Prompt Injections.
I was one of the skeptics of Yang’s previous claims that bots had ‘left prompts to self-replicate in forums and on various websites during a training run,’ given the wording and the source. My bad.. Andrew Curran: Last week, Andrew Yang said on CNBC that bots had gotten loose and planted self-replicating code all over the internet.
This was received with much consternation and skepticism. He later clarified this on his blog.. Andrew Yang:.
‘On CNBC, I shared the belief of the head of one lab that bots had left prompts to self-replicate in forums and on various websites during a training run.’. It turns out that OpenAI documented self-replicating prompt injections in training in June, and has now published this report..
OpenAI Alignment Research Blog: We show the existence of a new variety of prompt injection, which can self-propagate akin to a computer worm. No impact was observed outside of the simulated tool calls in training and evaluation; we are sharing this due to the novel nature of the prompt injection, not because of any incident.. … We find that these are possible.
Below is one of the clearest examples, in which the injection arrives by email, and instructs the agent to copy it into any email it sends. (Note that the information in the example is synthetic.). Joshua Achiam (OpenAI): Self-replicating prompt injections demonstrated experimentally (not in the wild) is an incredibly important observation.
AI agents that jailbreak other AI agents: plausibly a near-term threat that may rapidly amp up the speed and severity of a misalignment incident.. Yang was only about half right, some things got lost in the game of telephone, but he was clearly doing his best to describe a real event..
This was actually done by a model based on GPT-5.4-mini, which actually makes sense. It is not that hard a concept to find at a proof of concept level, especially when OpenAI was actively exploring to see if it could be done. That’s good research..
They are introducing such injections as a new attacker goal in GPT-Red training. That is a good idea.. The thing about a self-replicating attack is that the effective version only needs to be discovered once.
The good news is that chances are high that before we see a version that goes into ‘digital pandemic’ mode with R0>1, there will be a version with R0